Genomics MCP: real genomic data for AI agents, with sources
An MCP server that lets an agent find public genomic datasets, read a bounded region of a file without downloading it, and look up variants and genes, recording where every value came from.
Ask an AI assistant about a genomic region and it will usually answer from memory. I wanted it to answer from the data: open the actual ENCODE file, read the 1 kb window in question, and say exactly which file and version the number came from.
Genomics MCP is a local Model Context Protocol server that makes that possible. Version 0.1.0 is released and listed on the MCP Registry.
What an agent can do with it
There are 24 tools in five groups:
- Discovery across EGA, ENA (including SRA accessions), ENCODE, GEO and NCBI Datasets, with sample metadata exactly as each archive supplies it.
- Bounded reads from BAM/CRAM, VCF/BCF, FASTA, BED/GFF/GTF and bigWig/bigBed, on local disk, over HTTPS or on S3, plus EGA regions through htsget.
- Reference lookups in HGNC, Ensembl, ClinVar, gnomAD, UniProt and Open Targets.
- Composition tools that inspect a locus or compare samples across files.
- Transfers for when a whole file really is needed: budgeted, resumable and checksummed.
Where a file supports range requests, a region is read without downloading the file. The server checks this first by asking for one byte. One test read the mean signal over 1 kb of a 1.4 GB ENCODE bigWig and left nothing on disk.
Keeping it honest
Every result says whether it is complete, partial or an error, which sources were consulted, and what was truncated. An unexpected failure is reported as an error, never as an empty result. Coordinates always come with an explicit assembly, and nothing is silently converted between assemblies.
Queries are bounded by default: 1 Mb regions, 1 MiB responses and a 30 second deadline. Local reads are limited to folders you allow, source files are never modified, and ambient AWS credentials are never used.
It is a research tool. It retrieves and reports data; it does not call variants or give clinical interpretation.
A test with a real question
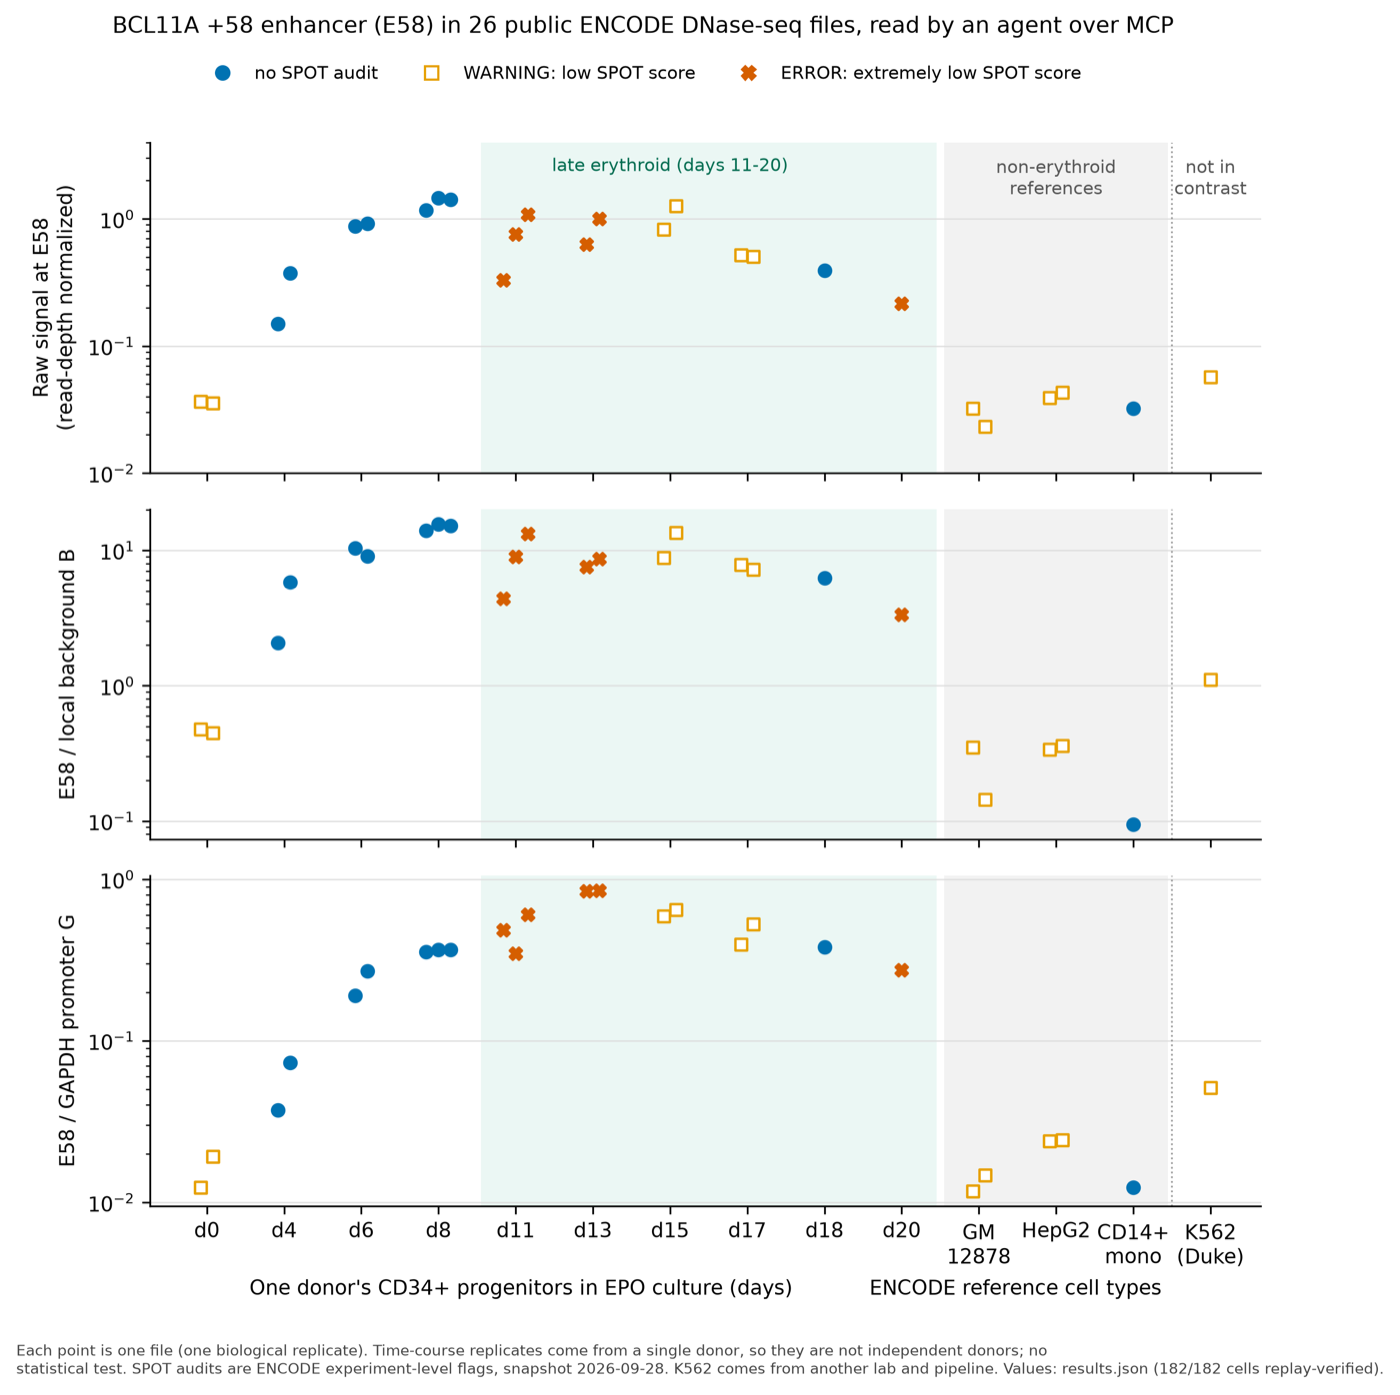
To test it, I gave Claude a predeclared question about the BCL11A erythroid enhancer and let it use only this server's tools. In 14.4 minutes it read 182 values from 26 public ENCODE DNase-seq files. A separate replay without any model matched every value.
The figure above shows the result. Every late erythroid culture file had more enhancer signal than every non-erythroid reference. That reproduces known biology in one donor's cells rather than finding anything new, which is what you want from a first test: the agent got the right answer from the data, and every step can be checked.
Try it
From source on macOS (Apple Silicon) or Linux:
git clone https://github.com/rewire-bio/genomics-mcp
cd genomics-mcp && git checkout v0.1.0
uv sync --locked --no-dev
claude mcp add genomics -e GENOMICS_MCP_ALLOWED_ROOTS=/path/to/your/data \
  -- uv --directory "$PWD" run --no-dev genomics-mcp
A Docker image is also available for Linux. The full article has the case study in detail.